Your devices are where
nobody is. That is where the engineering starts.
An unattended device cannot wait for a site visit. It has to stay alive on its own, take updates remotely, and recover by itself when something breaks. None of that is solved in the app — it lives in the Android platform underneath. That layer, on Qualcomm hardware, is what we do.
Your app on top, device management around it — the layer in between is ours
The end customer maintains one app. The board vendor brings the hardware, the device owner app and the cloud. Neither of them owns the Android layer in between — the SDK that lets the app reach I/O without platform work, the logic that decides which network path traffic takes when several coexist, the version upgrade when the vendor BSP stops moving, the memory and boot time an unattended device lives or dies by. That layer is what we build.
The product logic, the UI, the domain knowledge — their IP, and the reason the device exists. One app, which should not have to be rewritten because the board changed.
Board vendors bring their own device owner app, cloud service and update pipeline — that is their product and their recurring revenue. We do not sell a management platform and do not compete here. We make sure the Android underneath can actually be enrolled, locked down and updated by theirs.
Modem, ISP and RF calibration, signing keys, certification. Not our layer, and we say so up front — work that needs those things cannot be shipped without them.
Build it before it ships. Keep it alive after.
Most teams get stuck in the first half, then discover in the second half that there is no way back — the device has shipped, nobody is on site, and the update path was never designed in. These two halves have to be planned together; the second one cannot be bolted on from a distance.
Before it ships — making the device exist
Board bring-up, driver porting, HAL work, Android version upgrades, memory and boot-time reduction, edge-AI on the NPU. This is the part the SoC vendor and the board maker both leave to you.
After it ships — keeping it alive with nobody there
OTA releases, security patches, remote debugging over a private tunnel, fleet visibility, and self-recovery when a device wedges. If this was not designed in before shipment, there is no way to add it afterwards from a distance.
What we do not take on
One rule: anything that requires the silicon vendor’s signing keys, licensed tools, or proprietary calibration data, we decline. Not because it is hard — because taking it on without those things produces work you cannot ship.
We decline
- MIPI camera ISP / 3A tuning
- Battery charging curves, fuel gauge, safety certification
- Modem / aDSP / SLPI firmware and calibration
- RF calibration
- CTS / GTS and regulatory certification
- Widevine L1
- Production signing key custody
- Hardware design and component selection
Need Google Play and GMS? That requires a Google agreement plus per-model CTS/GTS approval. For those products we would point you at hardware that already carries the certification, rather than take the work.
These look adjacent — we do take them
- UVC / USB cameras and hot-plug recovery
- Vision AI pipelines end to end
- Inference on the on-chip NPU (public SDK)
- DSP fault diagnosis and configuration-layer fixes
- Power and thermal problem localization
- Audio codec, amplifier and routing bring-up
The line is not "hardware vs software". It is whether the work can be completed and verified without something only the vendor can give you.
Three Ways to Work With Us
Each engagement has a defined scope, deliverable, and acceptance — so you know exactly what you are buying before we start. Deep focus on the Qualcomm Android platform.
Paid Assessment
For teams that need the risk scoped before committing budget.
- Platform compatibility measured, not estimated — with a report you keep
- Capability inventory: what works on this board, what does not, what is unverified
- Problem localized to the right layer (HW / BSP / framework / app)
- Next step and scope — the basis for the follow-on quote
Rescue Sprint
For bring-up that is stuck, a platform unstable in the field, or integration that has stalled.
- Scoped fix within a fixed window
- Stabilized, repeatable system baseline
- Acceptance criteria and handover docs
Platform Maintenance Retainer
For devices already in the field that need ongoing ownership of platform availability.
- OTA release review and rollback readiness
- Diagnostics and remote recovery
- Field issue tracking and vendor coordination
Not sure which fits? Start with a Paid Assessment — it credits toward a follow-on engagement.
Every number below was measured on hardware
Client work, anonymized. Same device, same conditions, before and after — no ranges, no "up to", no "varies by scope". Where we do not have a measured number, there is no case here.
LTE that stopped dropping
A field device was changing IP roughly every 24 seconds and had no network at all for 16% of the time. The recorded cause was "modem power saving." It was not. The allowed radio-access list was too wide, so at the edge of coverage the modem kept retrying 3G and 2G, tearing the connection down each time.
The camera app the system kept killing
A 3 GB unattended device is healthy when idle — the risk only shows up under camera load, when buffer allocations spike and the kernel starts killing by score. It killed the customer camera app and left the process that caused the spike running. Per-app memory limits could not catch it: the kernel accounting they use does not include those buffers at all. So the fix was a watchdog that stops the actual culprit instead of waiting for the kernel to pick a victim.
When the vendor stops updating, the system layer is still yours
The board was stuck on Android 13, the vendor BSP was no longer maintained, and there was no source to work from — every problem became a wait for a release that was never coming. We replaced only the system image and left the vendor partition untouched: not one byte changed. Getting to a newer Android was the side effect; the point is that the system layer is yours to change again.
Cutting boot time by more than half
An unattended device that takes 34 seconds to come back after a power cut is 34 seconds of missing service, every time. Most of it turned out to be the kernel writing every log line to a serial console nobody was reading.
Object detection from 140 ms to 3 ms
A detection model ran on the CPU because moving it to the NPU made it slower, not faster. Offline per-operator profiling found a single pooling layer running 250× slower than expected on that accelerator; replacing it with an equivalent convolution unblocked the whole graph.
Making the OS fit the board you already have
The customer board had 2082 MB of usable space and the stock image needed more. Rather than repartition every unit in the field, we removed what an unattended industrial device never uses — consumer apps, unused runtime versions, virtualization support.
Technical Notes From the Problems We Actually See
These articles explain the engineering gaps behind industrial Android devices: BSP customization, network recovery, OTA, diagnostics, and long-term platform maintenance.
Who does the work
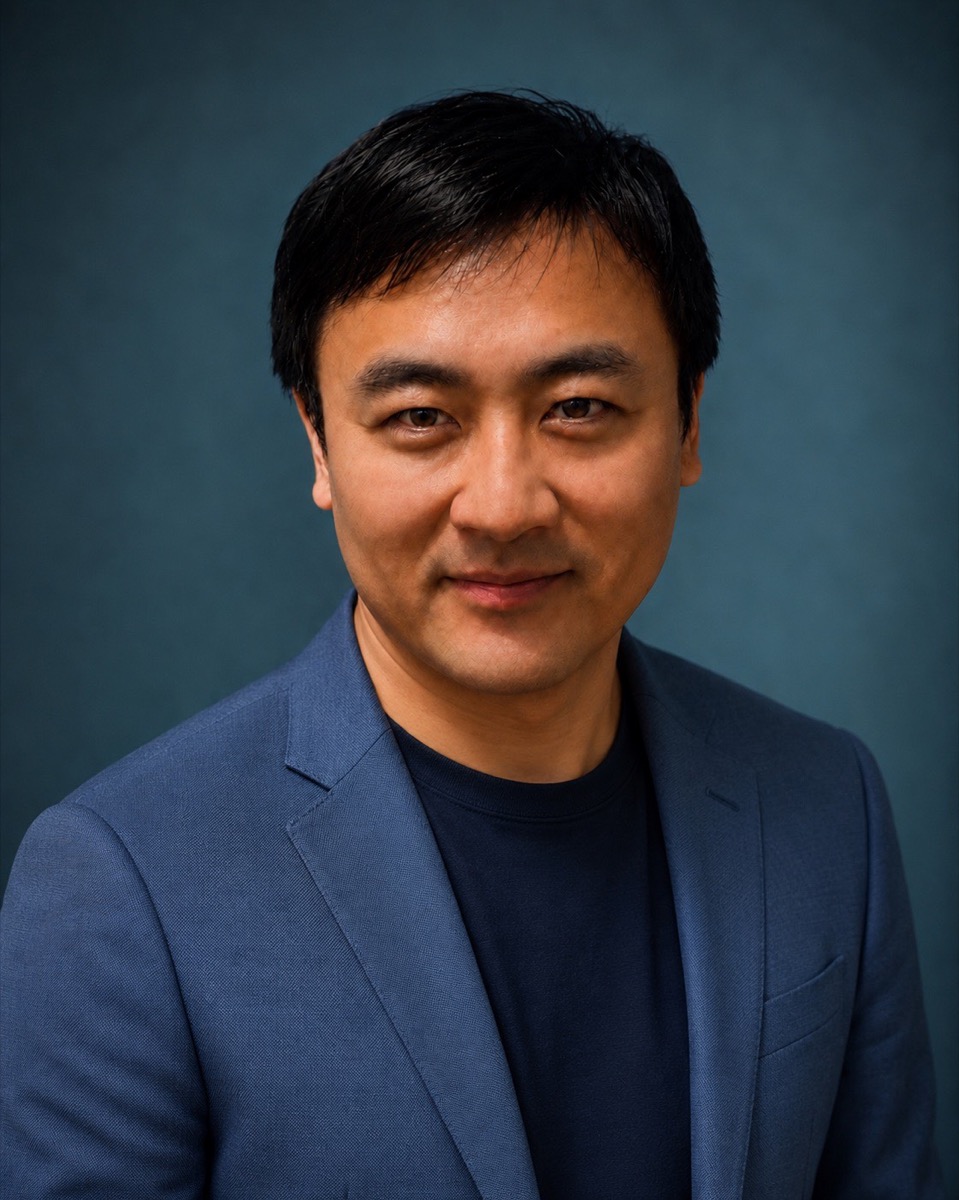
CoreEdge Lab is led by James Lee, with 17+ years across embedded systems, IC design support, Android BSP / SoC platform work, and production delivery. Clients usually come to us when the platform is already behind schedule, unstable in the field, or missing the system-layer ownership needed to ship. We work where those problems are actually solved: bring-up, integration, recovery, diagnostics, and production hardening.
Book an Initial Assessment
Tell us where the platform is stuck: bring-up, unstable networking, OTA, diagnostics, or production readiness. We'll reply within 24 hours with the most likely next step.